AI, vision & medical imaging33 stars on GitHub
QWOP with PPO
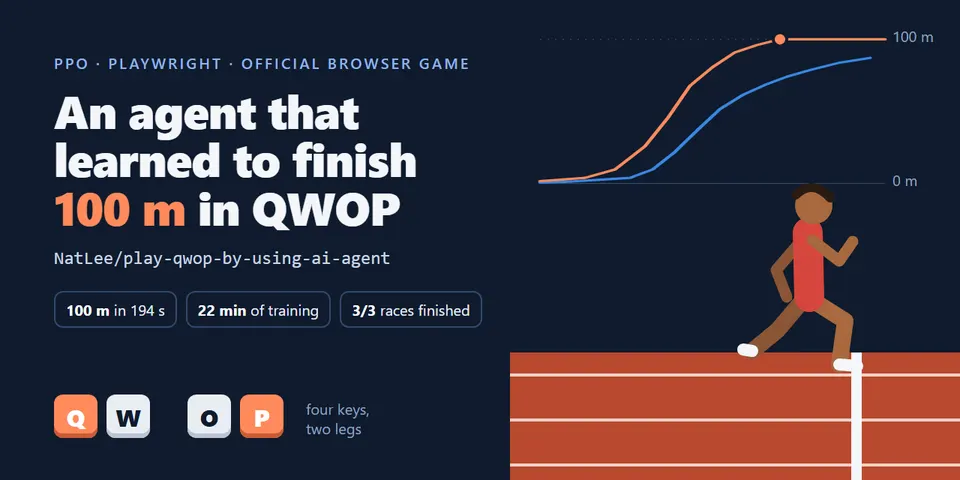
A PyTorch PPO agent plays the real QWOP browser game through Playwright. Six evaluation races, six 100 m finishes. Grace was not part of the reward function.
2019Completed
AI/ML
Compare sentiment models on the same terms
TF-IDF, embeddings, fine-tuned encoders and a local language model, evaluated on fixed splits across six sentiment datasets. The successor to GURA.
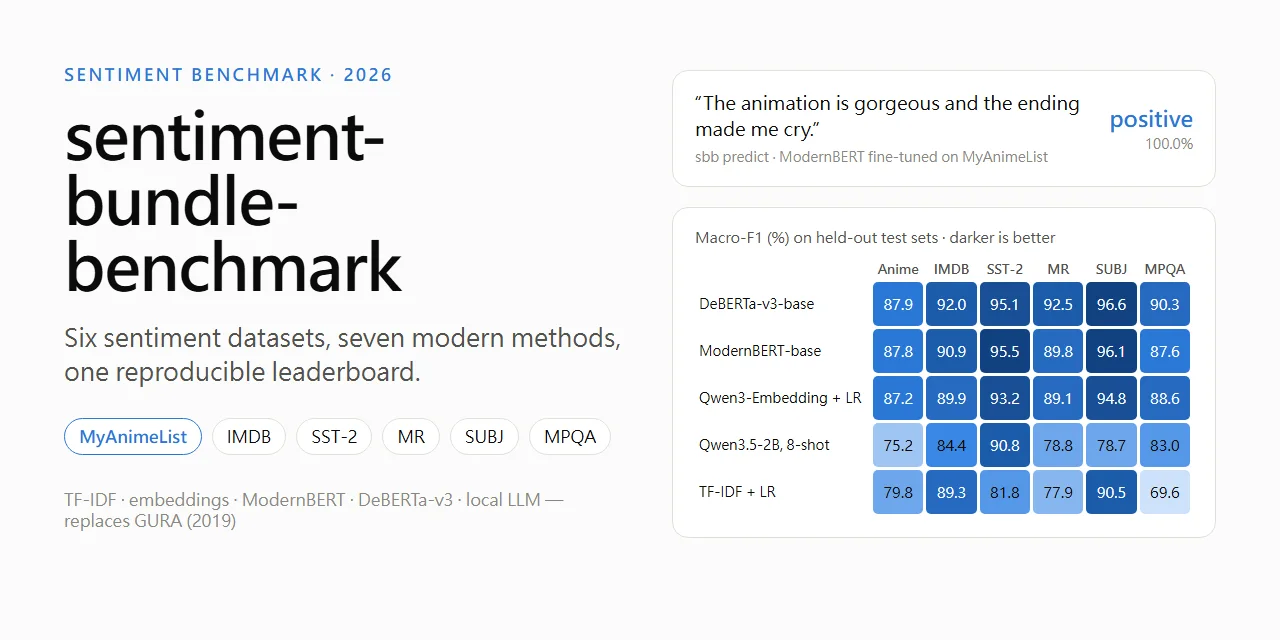
A reproducible sentiment-classification benchmark across MyAnimeList reviews and five classic English datasets. Fixed splits and seeds support comparisons of accuracy, macro-F1, training time, inference speed, memory and model size. It replaces the older GURA BiGRU experiment.
A PyTorch PPO agent plays the real QWOP browser game through Playwright. Six evaluation races, six 100 m finishes. Grace was not part of the reward function.
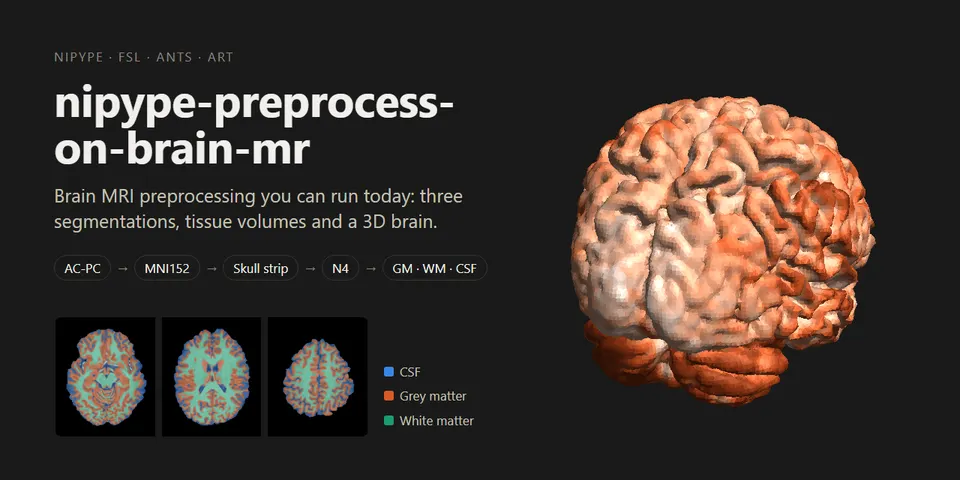
An end-to-end Nipype pipeline with FSL FAST, K-means and ANTs Atropos segmentation, tissue volumes, bias-correction metrics and an interactive 3D brain.
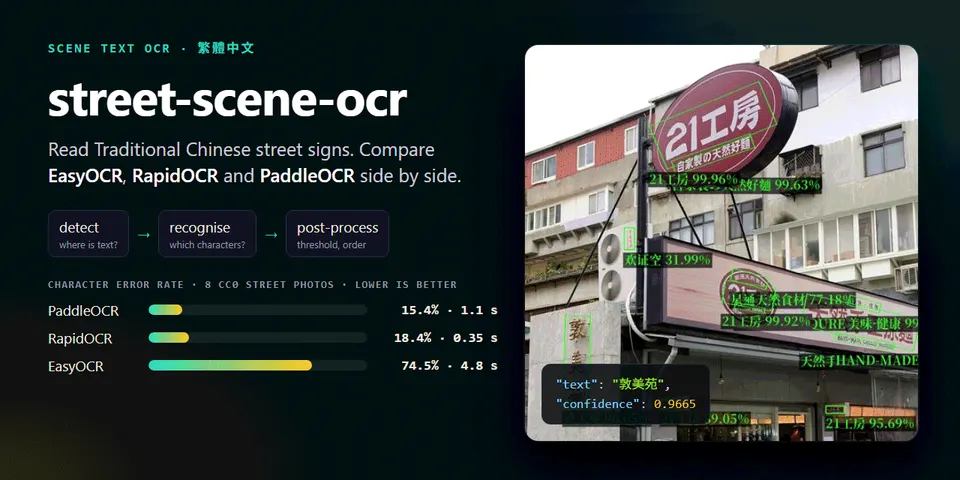
Compare EasyOCR, RapidOCR and PaddleOCR on Traditional Chinese street signs, with text boxes, timings and a small public-domain benchmark.